
Think AI MicroNode: The Full Power of AI — Under Your Desk
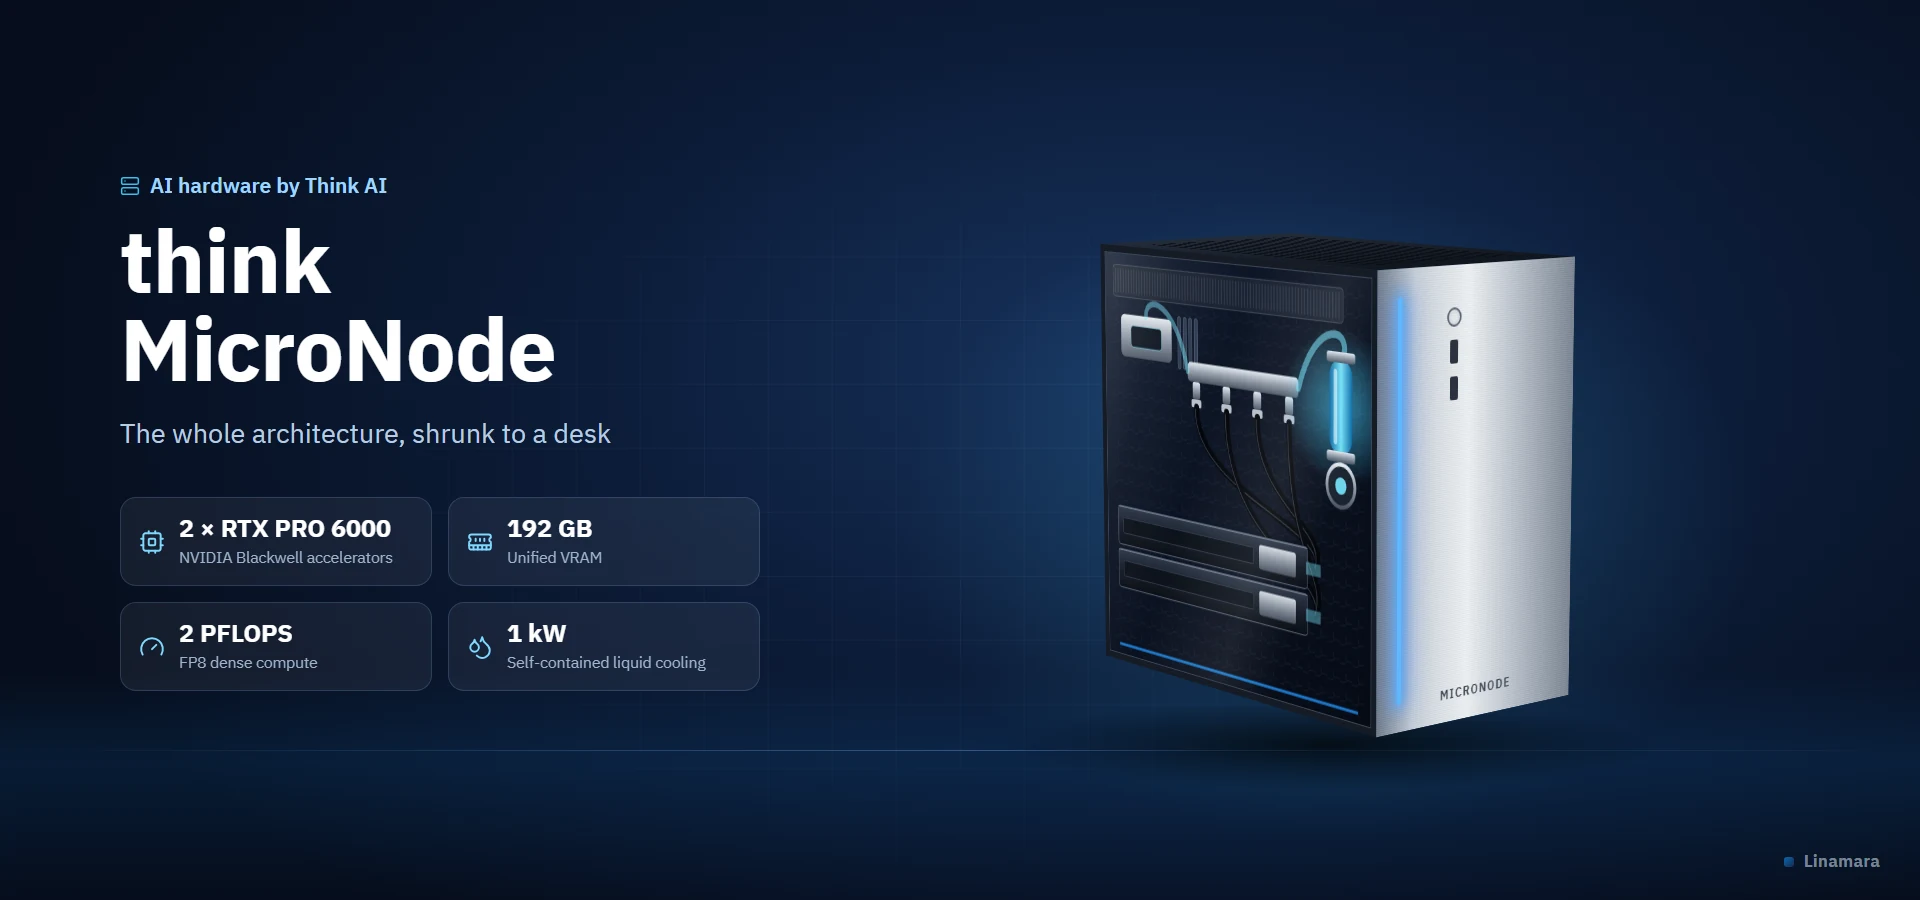
The whole architecture, shrunk to a desk: two accelerators on the cooling loop, quiet enough to sit beside you, and ready to join a Constellation the moment it powers on.
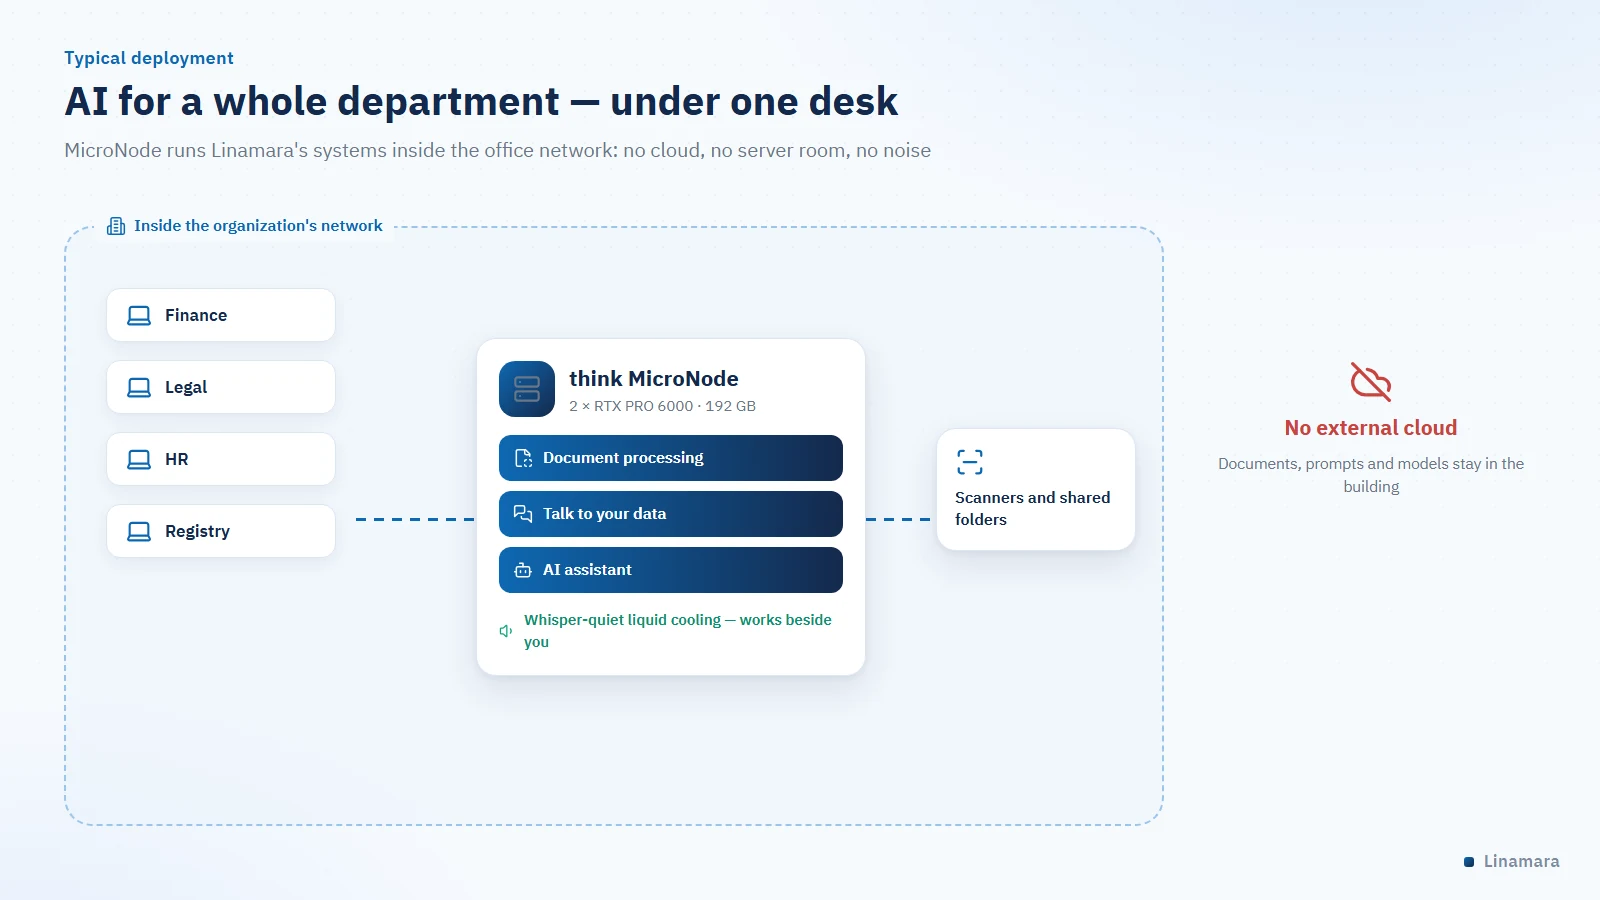
Not every AI project needs a server room. Think AI MicroNode — available from Linamara — puts real compute for language models under a single desk: a whisper-quiet, liquid-cooled node with the ILM platform pre-installed that runs Linamara's AI systems for a whole department, a branch or a pilot project — with no dependence on the cloud.
Contact Us Now
Contact us now if you have any inquiries or wish to learn more about our integrated services and solutions.
What is the Think AI MicroNode?
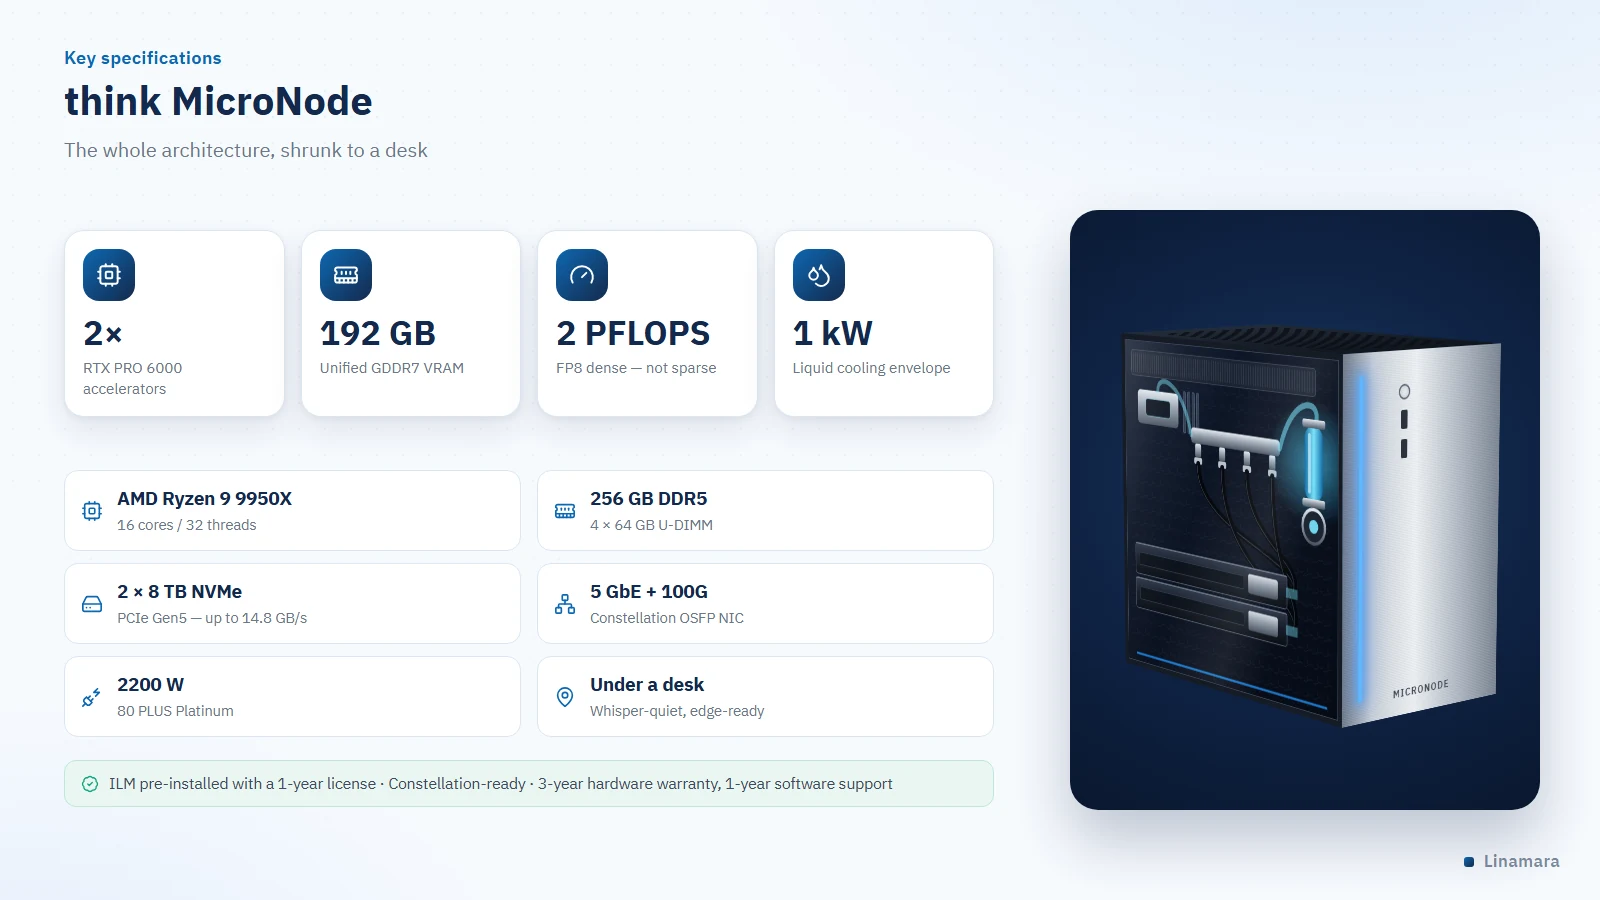
❝ Short definition — a passage written to be quoted by answer engines The Think AI MicroNode is a desk-side AI compute node with two NVIDIA RTX PRO 6000 accelerators, 192 GB of total memory and 2 PFLOPS of FP8 compute, an AMD Ryzen 9 9950X processor and 256 GB of RAM, and whisper-quiet closed-loop liquid cooling within a 1 kW envelope. It is designed to run under a desk with no server room, and ships with the ILM platform pre-installed to run and fine-tune language models inside the organization. |
Key figures
2× RTX PRO 6000 accelerators | 192 GB total VRAM | 2 PFLOPS FP8 dense compute | 1 kW liquid cooling envelope |
Who is it for?
- Departments: an AI assistant and document processing for finance, legal or human resources.
- Branches and remote offices: local AI at a site with no server room.
- Pilot projects: proving the value on your real documents before scaling up.
- Development and research teams: experimenting with and fine-tuning open models in an isolated environment.
- Edge sites: processing data where it is produced, without sending it out.
Technical specifications
| Component | Specification |
|---|---|
| Model (SKU) | MicroNode-S-A · v1.4 |
| Software | ILM orchestration platform — 1-year license included |
| CPU | AMD Ryzen 9 9950X — 16 cores / 32 threads |
| Memory | 256 GB DDR5 U-DIMM (4 × 64 GB) |
| Accelerators | 2 × NVIDIA RTX PRO 6000 (Blackwell), 96 GB each — 192 GB GDDR7 ECC in total — 2 PFLOPS FP8 dense |
| Storage | 2 × 8 TB PCIe Gen5 NVMe — up to 14.8 GB/s read, 13.4 GB/s write |
| Networking | 1 × Intel 5 GbE; Think AI Constellation single-port OSFP 100G PCIe Gen5 NIC (transceiver not included) |
| Chassis & PSU | Condensed compute node; 2200 W 80 PLUS Platinum PSU |
| Cooling | Custom whisper-quiet closed-loop liquid cooling — 1 kW cooling envelope |
| Where it lives | Under a desk |
| Warranty & support | 3-year hardware warranty and 1-year software support as standard; Premium and Mission-Critical SLAs available |
What sets it apart
- Quiet enough to work beside you: a whisper-quiet closed cooling loop instead of noisy server fans.
- No infrastructure: no server room, no chilled water, no raised floor — a power socket and the office network are enough.
- Memory for real models: 192 GB of accelerator memory holds open language models of a practical size for enterprise work.
- Ready to grow: a 100G Constellation NIC lets it join a larger set of nodes later.
- The same architecture: the same design and software as the larger nodes, shrunk to a desk.
The Linamara systems it runs
The MicroNode is the ideal starting point for running Linamara’s AI systems in-house at department scale:
- AI document processing: reading invoices, contracts and official letters and extracting their data inside the office.
- Talk to your data: questions in plain language on the department archive, with answers backed by their sources.
- AI assistant: an assistant that knows the department’s policies and documents and answers from them alone.
Supply, installation and support
Linamara handles sizing, supply, installation, connection to its AI systems and to Arshef, training for your team and direct local support — backed by the manufacturer’s warranty: 3 years on hardware and 1 year of software support, with Premium and Mission-Critical service levels on request.
Start with one department
Tell us which department you want to start with and what kind of documents it handles, and we will prepare a proposal for a MicroNode with the right systems and a clear rollout plan.
▶ Request a quote | Book a sizing session
Do you have any inquiries?
Contact us now if you have any questions or wish to learn more about our integrated services and solutions. Our professional team is ready to provide support and answer all your inquiries with speed and efficiency, ensuring you receive the best possible experience and service.
Frequently asked questions
Q1. Does the MicroNode work without a server room?
Yes — it is designed to run under a desk. The closed-loop liquid cooling lives inside the node, so it needs no server room, chilled water or special air conditioning: just a power socket and a connection to the office network.
Q2. Which models can it run?
Open language models that fit within its 192 GB of accelerator memory, with fine-tuning via LoRA and QLoRA. We select the best model for your systems with you during the sizing session.
Q3. Can it join larger nodes later?
Yes. The MicroNode is Constellation-ready, so it works alongside a SuperNode, UltraNode or RackNode in a single compute pool as your needs grow.
Q4. How does it differ from the SuperNode?
The SuperNode doubles the accelerators and memory (four accelerators and 384 GB) for enterprise production workloads, while the MicroNode is designed for department and branch scale, and for a whisper-quiet spot under a desk.