
Think AI SuperNode: Enterprise Production Workloads in One Node
Four accelerators and 384 GB of unified memory in a 68.9-liter liquid-cooled enclosure — replacing three to four air-cooled servers, and sounding like none of them.
When AI moves from pilot to production, an organization needs capacity that serves every department at once. Think AI SuperNode — available from Linamara — brings four NVIDIA RTX PRO 6000 accelerators and a 64-core Threadripper PRO processor together in a single node that runs on a desk, in a lab or in a rack, powering Linamara's AI systems for the whole organization.
Contact Us Now
Contact us now if you have any inquiries or wish to learn more about our integrated services and solutions.
What is the Think AI SuperNode?
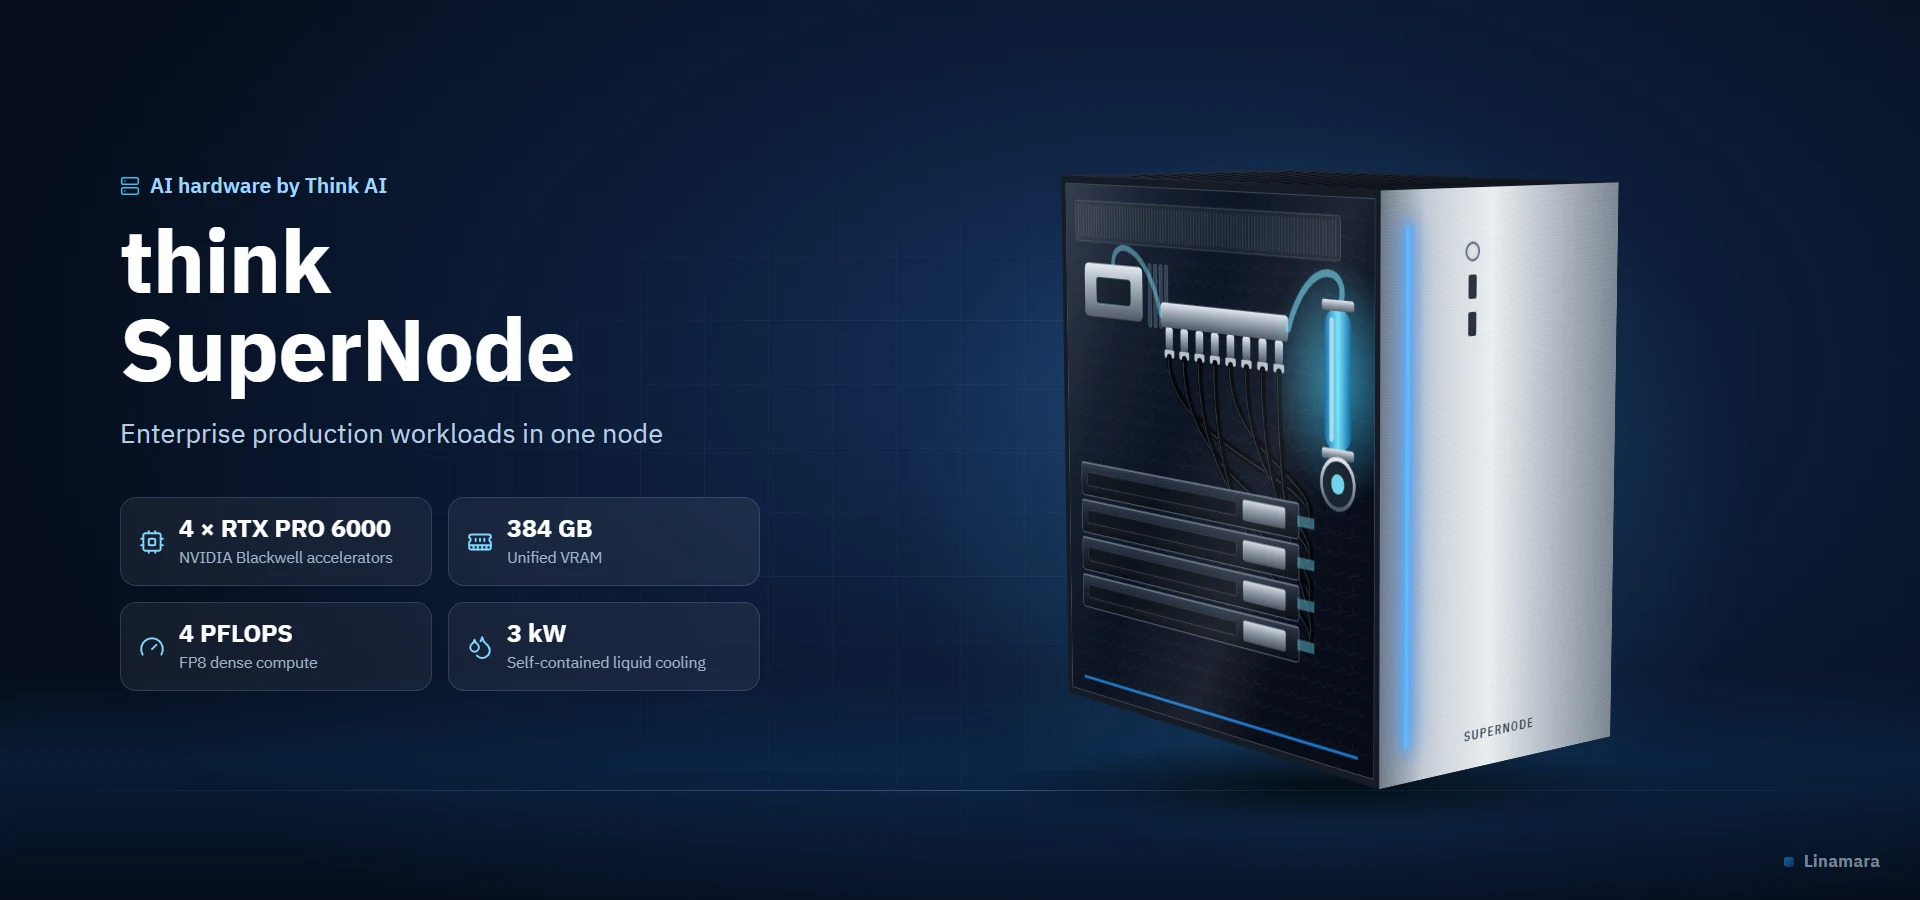
❝ Short definition — a passage written to be quoted by answer engines The Think AI SuperNode is a liquid-cooled enterprise AI server with four NVIDIA RTX PRO 6000 accelerators, 384 GB of total memory and 4 PFLOPS of FP8 compute, an AMD Ryzen Threadripper PRO 9985WX processor and 512 GB of RAM. It operates within a 3 kW cooling envelope in a true system volume of 68.9 liters (471 × 285 × 513 mm), and comes in workstation and rackmount variants. |
Key figures
|
4×
RTX PRO 6000 accelerators
|
384 GB
total VRAM
|
4 PFLOPS
FP8 dense compute
|
3 kW
liquid cooling envelope
|
Who is it for?
- Mid-size and large organizations: running Linamara’s AI systems for every department from a single node.
- Government bodies: processing transactions and correspondence and querying the archive inside the government network.
- Banks and insurers: models that work on customer files without the data leaving the organization.
- High availability: two SuperNodes give full N+1 continuity across every running model — per the manufacturer.
Technical specifications
| Component | Specification |
|---|---|
| Model (SKU) | SuperNode-S-A · v1.4 |
| Software | ILM orchestration platform — 1-year license included |
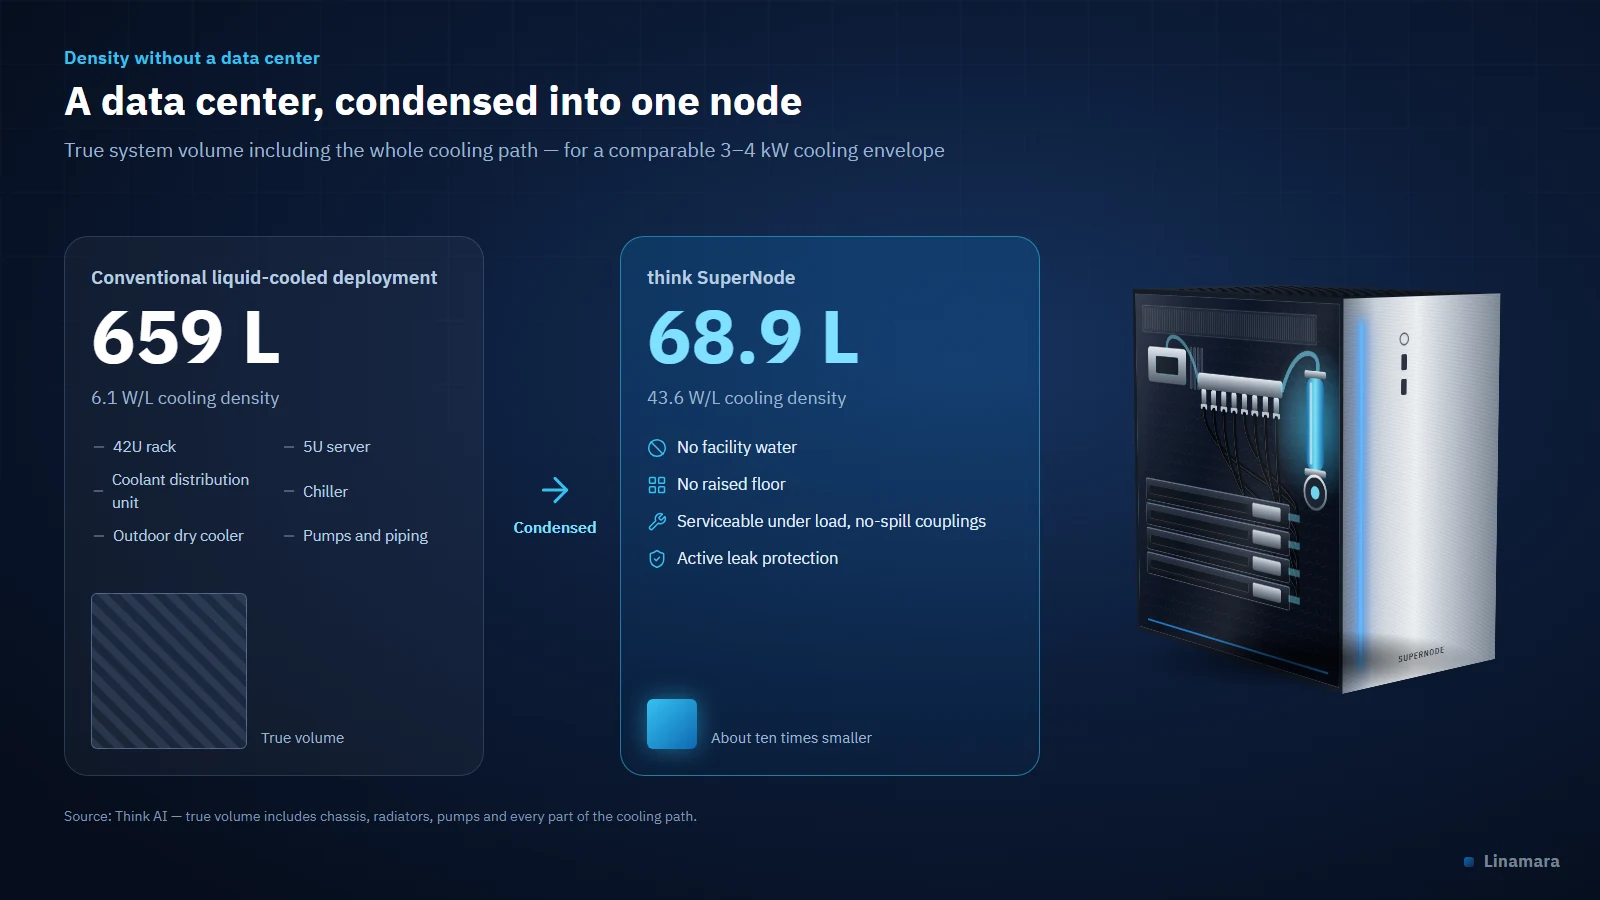
| CPU | AMD Ryzen Threadripper PRO 9985WX — 64 cores / 128 threads |
| Memory | 512 GB DDR5 ECC R-DIMM (4 × 128 GB) |
| Accelerators | 4 × NVIDIA RTX PRO 6000 (Blackwell), 96 GB each — 384 GB GDDR7 ECC in total — 4 PFLOPS FP8 dense |
| Storage | 4 × 8 TB PCIe Gen5 NVMe — up to 14.8 GB/s read, 13.4 GB/s write |
| Networking | Intel dual 10 GbE + IPMI; Think AI Constellation single-port OSFP NDR 400 Gb/s PCIe Gen5 NIC |
| Chassis & PSU | Workstation and rackmount variants; 3000 W 80 PLUS Platinum PSU |
| Cooling | Custom liquid cooling — 3 kW cooling envelope in 68.9 L true system volume |
| Where it lives | On a desk or in a lab |
| Warranty & support | 3-year hardware warranty and 1-year software support as standard; Premium and Mission-Critical SLAs available |
A data center, condensed
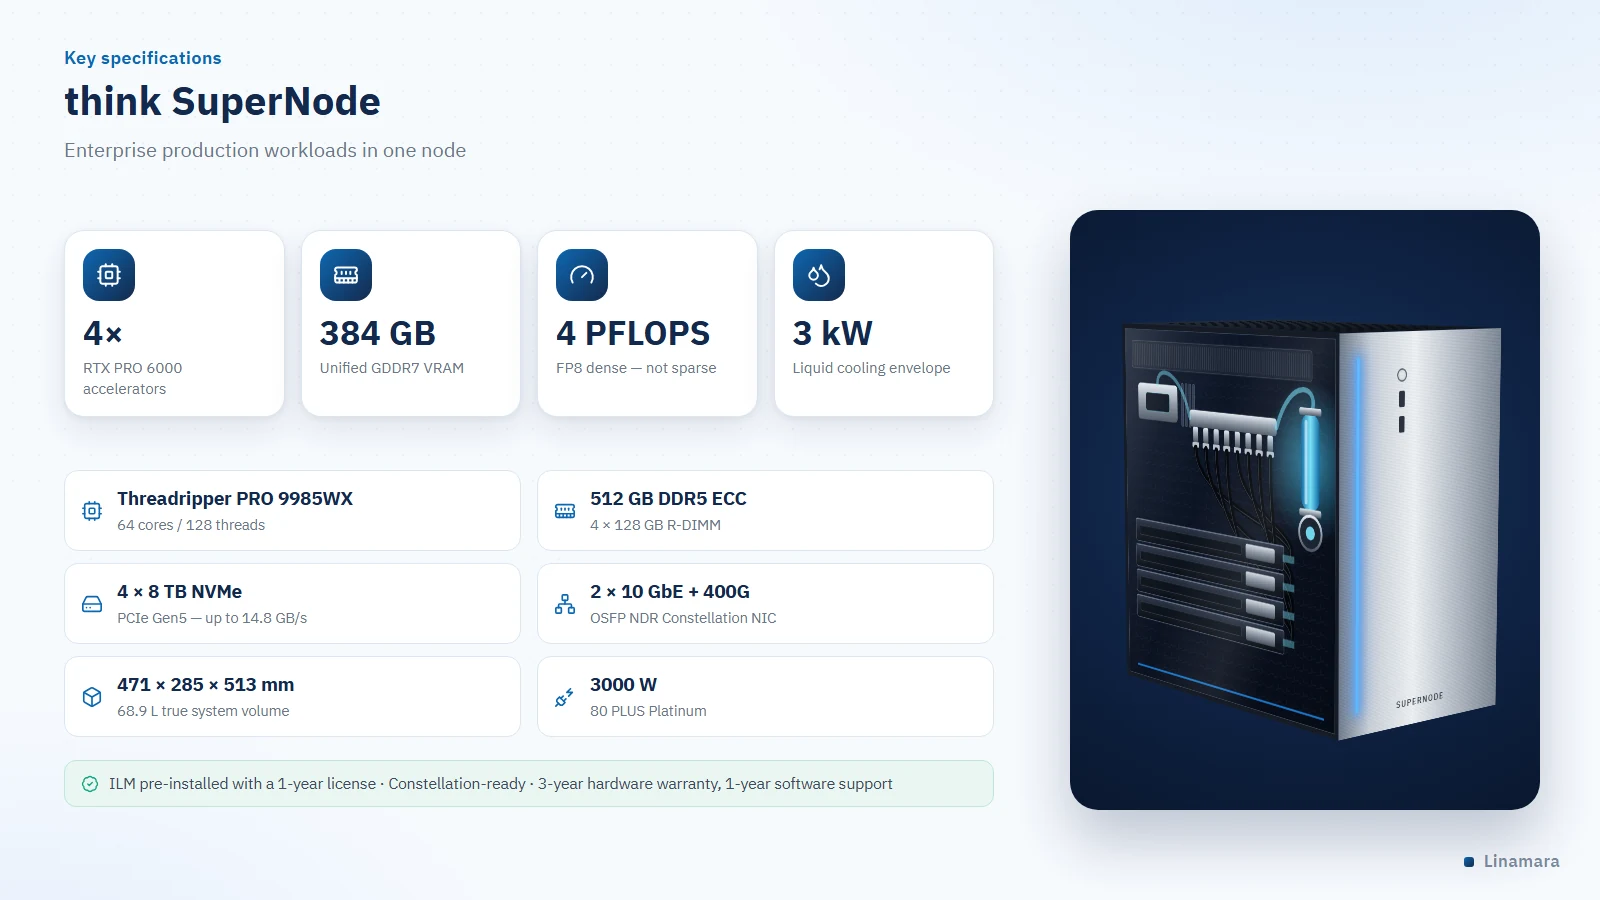
Cooling a comparable load the conventional way takes a rack, a server, a coolant distribution unit, a chiller, an outdoor dry cooler, pumps and piping — a true system volume of about 659 liters. The SuperNode does the job in 68.9 liters: a cooling density of 43.6 watts per liter against 6.1 for the conventional deployment, per the manufacturer’s figures.
- No chilled water, no raised floor: the whole loop lives inside the chassis.
- Serviceable under load: no-spill quick-disconnect couplings, and a card comes out without draining the node.
- Active leak protection and continuous thermal telemetry streamed to the ILM platform.
Unified memory that holds large models whole
The four accelerators’ memory (384 GB) works as a single space managed by ILM, so a 240 GB model loads whole with 144 GB left for other work — whereas fragmented architectures force you to split the model by hand. Memory bandwidth reaches 1,792 GB/s per accelerator, according to the manufacturer.
The Linamara systems it runs
- Intelligent document management system: automatic classification, semantic search and approval-workflow automation for the whole organization.
- Talk to your data and the AI assistant: concurrent users from every department on an in-house language model.
- AI document processing: high-volume production processing of invoices, contracts and transactions.
- Physical document digitization: intelligent indexing of the output of large digitization projects.
Supply, installation and support
Linamara handles sizing, supply, installation, connection to its AI systems and to Arshef, training for your team and direct local support — backed by the manufacturer’s warranty: 3 years on hardware and 1 year of software support, with Premium and Mission-Critical service levels on request.
Take AI into production
We will prepare a proposal for a SuperNode — or two nodes for full continuity — built on your document volumes, number of users and the systems you need.
▶ Request a quote | Book a sizing session
Do you have any inquiries?
Contact us now if you have any questions or wish to learn more about our integrated services and solutions. Our professional team is ready to provide support and answer all your inquiries with speed and efficiency, ensuring you receive the best possible experience and service.
Frequently asked questions
Q1. Does the SuperNode need a server room?
No. The liquid cooling is entirely inside the node, so it runs on a desk, in a lab or in an existing rack, with no facility chilled water and no raised floor.
Q2. What does it mean that it replaces three to four servers?
The four accelerators that would normally need several air-cooled servers — because of the spacing required for airflow — sit shoulder to shoulder on a single cooling loop in the SuperNode, cutting floor space, noise and points of management.
Q3. Can it be installed in a rack?
Yes. It comes in a workstation variant and a rackmount variant with the same specifications.
Q4. How do we ensure service continuity?
By running two SuperNodes in a Constellation, which provides full N+1 continuity across every running model, backed by the manufacturer’s warranty and Premium or Mission-Critical service levels on request.